Build a YouTube Channel Monitoring Agent That Summarizes New Uploads
If you follow a handful of YouTube channels for work, you miss uploads, and watching them all takes hours a week. This guide builds a small Python agent that checks any list of channels for new videos, pulls each new transcript, summarizes it with OpenAI or Claude, and posts the summary to Slack. Checking for new uploads is free, so you only spend credits when a channel actually publishes something.
You will get working code, a cron line, a GitHub Actions workflow, and the cost math.
What a monitoring agent is good for
- Competitor tracking. Know what rivals announced this week without watching every video.
- Industry trends. Follow 20 people in your field and see which topics keep coming up.
- Repurposing your own channel. Turn each new upload into a blog draft, social posts or newsletter copy.
- Client reporting. Agencies can run one channel list per client and send a weekly summary.
- Research. Follow lecture series and conference channels as they publish.
How the agent works
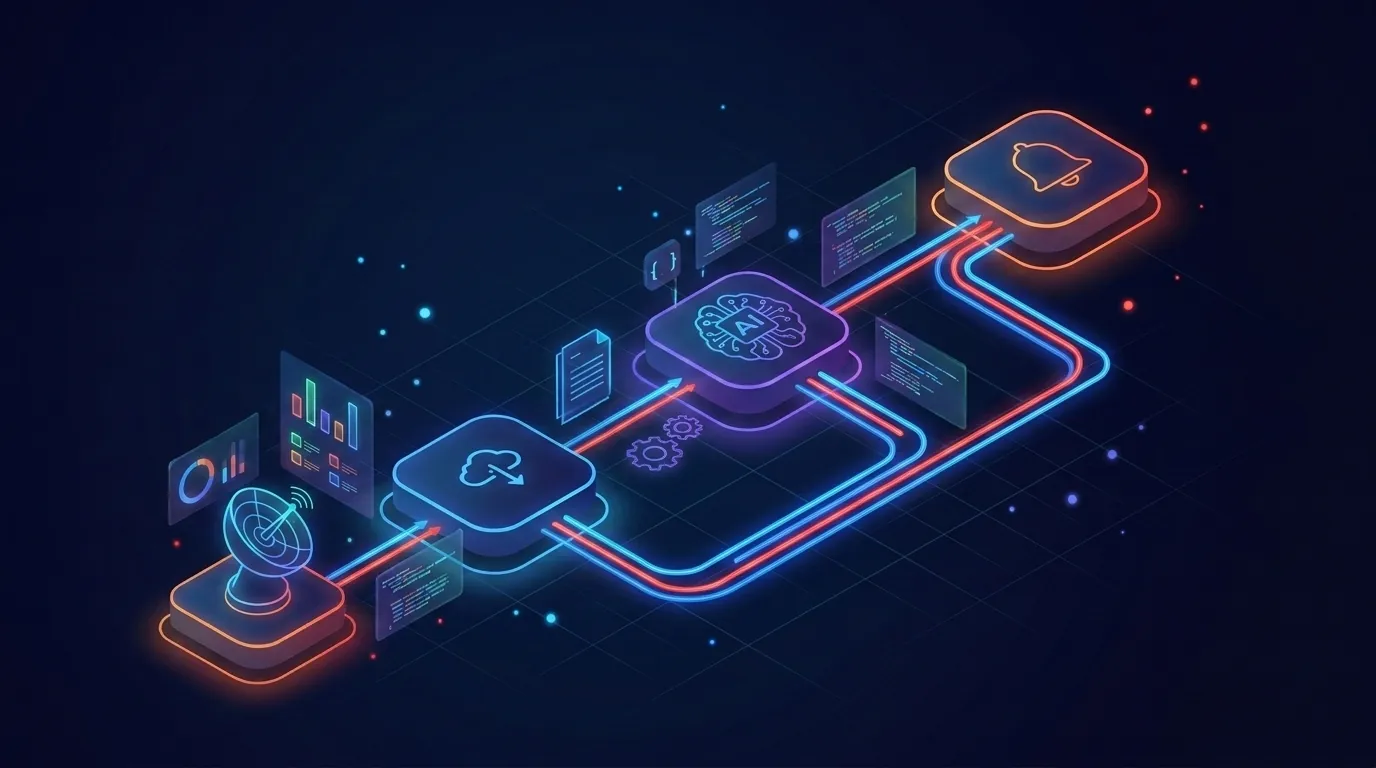
The loop has five steps:
- Take a list of channels (
@handles, channel URLs orUC…IDs). - Check each channel's latest 15 uploads on a schedule. Free.
- Compare with a small state file to find videos you have not handled yet.
- Fetch the transcript of each new video (1 credit) and summarize it with an LLM.
- Post the summary to Slack, email or n8n.
Steps 2 and 3 run constantly and cost nothing. Credits are only spent in step 4, and only when something new appeared.
Why channel/latest (free) and not channel/videos (paid)
TranscriptAPI has two ways to list a channel's videos:
GET /youtube/channel/latestreads the channel's RSS feed and returns the latest 15 uploads with titles and publish times. It costs 0 credits.GET /youtube/channel/videospages through the full upload history (videos, Shorts or live streams). It costs 1 credit per page.
For monitoring you only need the newest uploads, so use channel/latest. Use channel/videos once if you want to backfill a channel's history.
Set up your TranscriptAPI account
Sign up at transcriptapi.com to get an API key and 100 free credits, no card required. Free endpoints such as channel/latest need an account with at least one credit left. After the free credits, the Monthly plan is $5 for 1,000 credits a month (200 requests a minute), and the Annual plan is $54 a year for 1,000 credits a month (300 requests a minute) with cheaper top-ups. Failed requests are not charged.
Set TRANSCRIPTAPI_KEY, OPENAI_API_KEY (or ANTHROPIC_API_KEY) and SLACK_WEBHOOK_URL in your environment. Everything below goes in one file, agent.py:
import json
import os
from pathlib import Path

import requests

API = "https://transcriptapi.com/api/v2"
HEADERS = {"Authorization": f"Bearer {os.environ['TRANSCRIPTAPI_KEY']}"}
STATE_FILE = Path("state.json")

CHANNELS = ["@veritasium", "@Fireship", "@TwoMinutePapers"]
Step 1: Choose channels (resolving handles is optional)
channel/latest accepts an @handle, a channel URL or a UC… ID, so you can use handles directly. If you want stable IDs in your state file (handles can change), resolve each one once with the free channel/resolve endpoint and store the result:
def resolve_channel(handle_or_url: str) -> str:
    """@handle or channel URL -> UC... channel ID. Free (0 credits)."""
    r = requests.get(f"{API}/youtube/channel/resolve", params={"input": handle_or_url},
                     headers=HEADERS, timeout=10)
    r.raise_for_status()
    return r.json()["channel_id"]
Step 2: Check for new uploads
Poll each channel and compare against the video IDs you have already handled. The response lists videos in results, newest first, each with a videoId, title and published time.
def load_state() -> dict:
    return json.loads(STATE_FILE.read_text()) if STATE_FILE.exists() else {}

def save_state(state: dict) -> None:
    STATE_FILE.write_text(json.dumps(state, indent=2))

def latest_uploads(channel: str) -> list[dict]:
    """Latest 15 uploads via RSS, newest first. Free (0 credits)."""
    r = requests.get(f"{API}/youtube/channel/latest", params={"channel": channel},
                     headers=HEADERS, timeout=10)
    r.raise_for_status()
    return r.json()["results"]

def new_videos(channel: str, seen: list[str]) -> list[dict]:
    videos = latest_uploads(channel)
    if not seen:                      # first run: only the most recent video
        return videos[:1]
    return [v for v in videos if v["videoId"] not in seen]
On the first run the agent only picks up each channel's most recent video, so you do not get 15 alerts per channel. After that, the state file stores recent IDs per channel.
For more on the channel endpoints, see the channel videos API guide.
Step 3: Fetch the transcript
This is the only paid step, and it only runs for new videos.
def get_transcript(video_id: str) -> dict | None:
    """Plain-text transcript plus video length. 1 credit, charged only on success."""
    r = requests.get(
        f"{API}/youtube/transcript",
        params={"video_url": video_id, "format": "text", "include_timestamp": "false"},
        headers=HEADERS,
        timeout=30,
    )
    if r.status_code == 404:          # no captions, private or deleted: not charged
        return None
    r.raise_for_status()
    return r.json()                   # includes "transcript" and "length_seconds"
The response also includes length_seconds, which the loop below uses to skip Shorts and live streams.
Step 4: Summarize with OpenAI or Claude
Use whichever model you already pay for. The OpenAI version:
from openai import OpenAI

oa = OpenAI()

def summarize_openai(title: str, transcript: str) -> str:
    resp = oa.chat.completions.create(
        model="gpt-4o-mini",
        temperature=0.2,
        messages=[{"role": "user", "content":
                   "Summarize this YouTube video in 5 specific bullets.\n\n"
                   f"TITLE: {title}\n\nTRANSCRIPT:\n{transcript[:60000]}"}],
    )
    return resp.choices[0].message.content
The Claude version:
import anthropic

cl = anthropic.Anthropic()

def summarize_claude(title: str, transcript: str) -> str:
    msg = cl.messages.create(
        model="claude-haiku-4-5",
        max_tokens=600,
        messages=[{"role": "user", "content":
                   "Summarize this YouTube video in 5 specific bullets.\n\n"
                   f"TITLE: {title}\n\nTRANSCRIPT:\n{transcript[:60000]}"}],
    )
    return msg.content[0].text
The 60,000-character cap keeps most videos in one request. Long podcasts may need chunking or a model with a larger context window.
For competitor tracking, a structured weekly report often works better than per-video bullets. Collect the week's transcripts and send them with a prompt like this:
Analyze these YouTube transcripts and produce a report:
1. Key topics covered (and which video each came from)
2. Notable announcements or claims
3. Products and tools mentioned
4. What formats or angles seem to be working
5. Recommended actions for our team
Be specific. Use bullet points.
Change the prompt to change the output: compare this week's topics with last week's for trend tracking, or ask for a blog outline and three social posts for repurposing. The summarizer step is the same pattern as our video summarizer tutorial.
Step 5: Send it to Slack
Create an Incoming Webhook in your Slack workspace, then post the summary:
SLACK_URL = os.environ["SLACK_WEBHOOK_URL"]

def notify_slack(channel: str, video: dict, summary: str) -> None:
    text = (f"*New video from {channel}*\n"
            f"<https://youtu.be/{video['videoId']}|{video['title']}>\n\n{summary}")
    requests.post(SLACK_URL, json={"text": text}, timeout=10)
For email, use smtplib or a transactional email service. For n8n, send the payload to an n8n webhook and route it from there.
The full loop:
def run_once() -> None:
    state = load_state()                       # {channel: [video IDs already handled]}
    for channel in CHANNELS:
        seen = state.get(channel, [])
        for video in reversed(new_videos(channel, seen)):   # oldest first
            data = get_transcript(video["videoId"])
            length = data.get("length_seconds") if data else None
            if data and length and length >= 60:            # skip Shorts and live streams
                summary = summarize_openai(video["title"], data["transcript"])
                notify_slack(channel, video, summary)
            seen = ([video["videoId"]] + seen)[:50]           # remember recent IDs only
            state[channel] = seen
            save_state(state)                  # save after each video: no double alerts

if __name__ == "__main__":
    run_once()
Videos are handled oldest first, so alerts arrive in order. State is saved after every video, so a crash never sends the same summary twice.
Schedule it
Option A: cron on a server
*/30 * * * * cd /home/me/yt-agent && /usr/bin/python3 agent.py >> agent.log 2>&1
Every 30 minutes, with a log file. You are responsible for keeping the server running and noticing when the script fails.
Option B: GitHub Actions
No server needed. Runners start clean each time, so the workflow caches state.json between runs:
name: yt-agent
on:
  schedule:
    - cron: "*/30 * * * *"
  workflow_dispatch:

jobs:
  run:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - uses: actions/setup-python@v5
        with:
          python-version: "3.12"
      - uses: actions/cache@v4          # keep state.json between runs
        with:
          path: state.json
          key: yt-agent-state-${{ github.run_id }}
          restore-keys: yt-agent-state-
      - run: pip install requests openai anthropic
      - run: python agent.py
        env:
          TRANSCRIPTAPI_KEY: ${{ secrets.TRANSCRIPTAPI_KEY }}
          OPENAI_API_KEY: ${{ secrets.OPENAI_API_KEY }}
          SLACK_WEBHOOK_URL: ${{ secrets.SLACK_WEBHOOK_URL }}
GitHub may delay scheduled runs at busy times, and on private repositories the minutes count against your plan's included Actions minutes.
Option C: n8n or an agent platform
In n8n, use a Schedule Trigger, HTTP Request nodes for the two TranscriptAPI calls, an OpenAI node and a Slack node; no code needed. A managed agent platform such as CRHQ can also run the workflow on a schedule and keep its state between runs.
What it costs
Checking for uploads is free, so the cost depends on how many new videos your channels publish:
| Setup | New videos a month | Credits | Monthly plan | Annual plan |
|---|---|---|---|---|
| 10 channels, 2 videos a week each | about 87 | about 87 | $5 (1,000 included) | $4.50 |
| 100 channels, 5 new videos a day across all of them | about 150 | about 150 | $5 | $4.50 |
| 100 channels that each publish daily | about 3,000 | about 3,000 | $10 ($5 + 2 top-ups at $2.50) | $7.50 ($4.50 + 2 top-ups at $1.50) |
Polling 100 channels every 30 minutes is about 144,000 checks a month. On channel/latest that costs 0 credits. Done with channel/videos at 1 credit per page, the same checks would be about 144,000 credits a month. The 100 free credits cover a first test; ongoing monitoring needs a plan, because free endpoints require an account with credits.
Edge cases
- Live streams and premieres can appear in the feed before or while they air. Their
length_secondsis empty, so the loop skips them and marks them as handled. If you want the replay, leave live IDs out of the state file and check them again on a later run. - Shorts are regular uploads in the feed. The loop skips anything under 60 seconds; remove that check if you want them.
- Private or deleted videos return 404 on the transcript request and are not charged. The loop records them as handled and moves on.
- Many channels are just a longer list. The state file is keyed by channel, so channels never interfere with each other.
Going further
Once transcripts arrive on a schedule, you have a data pipeline. Feed them into a RAG pipeline to ask questions across months of videos ("What did competitors say about pricing this quarter?"). Or give an assistant direct access to YouTube data through an MCP server; our guide to connecting a YouTube MCP server to Claude covers the setup.
Put it into action
- Sign up at transcriptapi.com and copy your API key (100 free credits, no card).
- Pick 3 to 10 channels to start.
- Put the code above into
agent.pyand set the environment variables. - Run it once by hand and check that a Slack message arrives for one channel's latest video.
- Schedule it with cron, GitHub Actions or n8n.
- Tune the summary prompt, then add channels.
Which channels would you start with?
Frequently Asked Questions
- How does the agent detect new uploads without spending credits?
- It polls TranscriptAPI's channel/latest endpoint, which reads a channel's RSS feed and returns its latest 15 uploads for 0 credits. The agent compares the results with a small state file and only fetches a transcript, for 1 credit, when a video it has not seen appears.
- Why use channel/latest instead of channel/videos for monitoring?
- Monitoring only needs the newest uploads. channel/latest returns the latest 15 for free. channel/videos pages through a channel's full history at 1 credit per page, which is the right tool for a one-time backfill, not for checking every 30 minutes.
- How much does it cost to monitor 100 YouTube channels?
- Checking for uploads is free, so you pay only for transcripts of new videos: 1 credit each. If the 100 channels publish about 150 videos a month in total, that fits in the $5 Monthly plan's 1,000 credits. If each channel publishes daily (about 3,000 videos a month), it is about $10 a month on the Monthly plan.
- How do I run the agent automatically?
- Run it every 30 minutes with cron on a server, with a GitHub Actions scheduled workflow that caches the state file between runs, or with an n8n Schedule Trigger. Each run checks for new videos, summarizes any it finds and posts to Slack.